Try reloading the player or open this episode directly on YouTube.
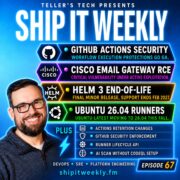
This episode of Ship It Weekly discusses new GitHub Actions workflow execution protections, enhancing security by controlling who can trigger workflows. It also covers Cisco's critical email gateway vulnerabilities, Helm 3's end-of-life, and the upcoming Ubuntu runner transition.
Now Playing
GitHub Actions Security, Cisco Email Gateway RCE, Helm 3 End-of-Life, Ubuntu 26.04 Runners & Why “Nothing Changed” Is Never the Whole Story
Ship It Weekly
0:0015:33
Chapters
Jump to a section in this episode.
Speed & share
Transcript
GitHub is adding new controls around who can
actually execute your Actions workflows. Helm
3 has reached its final minor release and is
officially on the road to end of life. And if
your builds use ubuntu-latest, the operating
system underneath them is about to change whether
you touch the workflow or not. I'm Brian Teller
from Teller's Tech, and this is Ship It Weekly.
Welcome back to Ship It Weekly, the show about
the DevOps, SRE, cloud, platform, and security
stories that matter when you are the person keeping
the thing running at three in the morning. For
the weekly story list and source links, check
out OnCallBrief.com. For past episodes and show
notes, head over to ShipItWeekly.fm. This week,
GitHub Actions gets new workflow execution protections.
Cisco has a critical Secure Email Gateway vulnerability
under active exploitation. Helm 3 has reached
its final minor release. And GitHub's Ubuntu
latest runner is moving from Ubuntu 24.04 to
26.04. Then we have a quick lightning round
and a human closer about one of my favorite phrases
during an incident. But nothing changed. Let's
get into it. First up, GitHub Actions workflow
execution protections are now generally available.
Last week, we talked about GitHub tightening
cache permissions. This week, they are moving
one step earlier in the process. Who should be
allowed to start the workflow in the first place?
Execution protections let organizations create
rules around both the actor and the event triggering
a workflow. Normal CI might be available to everybody,
while a manually triggered deployment is limited
to maintainers. Dependabot might be allowed to
trigger one workflow, but not another. And your
production deployment workflow can have completely
different rules from your normal test workflow.
The protections can target individual workflow
files too. So deploy.yml can have stricter
rules without applying those restrictions to
everything else. There is also an evaluate mode.
That means that you can see what the policy would
block before actually enforcing it. For platform
teams managing hundreds of repositories, that
is important. You can find legitimate exceptions
before turning on a security control and breaking
a bunch of pipelines. There is also a REST API,
so this can be managed programmatically. And
then there is pull_request_target. We talked
about that last week because GitHub's new cache
permissions specifically restrict cache access
for lower-trust events like pull_request_target.
GitHub is going further now. Starting November
2nd, affected public repositories without their
own applicable event policy will have pull request
target disabled by default. If you legitimately
need it, you can explicitly allow it. So the
important change here is not another explanation
of pull_request_target. It is that GitHub is
continuing to make CI trust boundaries explicit.
Last week, what can the workflow access? this
week should the workflow execute at all. Your
CI system may have cloud credentials, registry
access, signing keys, or deployment permissions.
Being allowed to contribute code should not automatically
mean being allowed to execute every piece of
automation attached to it. Next, Cisco has released
security updates for Secure Email Gateway and
Secure Email and Web Manager. There are multiple
vulnerabilities involved, including several critical
issues. The one getting the most attention is
CVE-2026-76461. It is a SQL injection vulnerability
in the email parsing logic of Cisco secure email
gateway. An unauthenticated attacker can exploit
it by sending a specially crafted email through
an affected device. Successful exploitation can
lead to arbitrary commands running as root. And
Cisco says the vulnerability is already being
actively exploited. There are no workarounds.
You need to upgrade to a fixed release. What
makes this interesting is where the vulnerability
lives. Email security gateways exist specifically
to process untrusted content coming from the
internet. Attachments, headers, URLs, message
bodies, all of that parsing creates attack surface.
The same is true for firewalls, VPN concentrators,
proxies, and other security appliances. The thing
protecting the boundary is also sitting directly
on the boundary. And these systems have a habit
of becoming infrastructure furniture. They are
critical, they work, and nobody wants to touch
them. So upgrades get delayed. Eventually, the
security appliance protecting everything else
becomes one of the oldest systems in the environment.
If you run Cisco Secure Email Gateway, check
your version and get onto a fixed release. Security
software is still software. And sometimes, the
thing inspecting the attack becomes the attack
path. Third, Helm 3 has reached its final minor
release. From here, Helm 3 is basically in security
maintenance mode. Helm 4 has been available since
November, and Helm 3 continues receiving security
fixes through February 10, 2027. After that,
support ends. That does not mean that everybody
needs to migrate this weekend. But if Helm is
deeply embedded in your platform, the clock has
officially started. The good news is that Helm
4 maintains compatibility with most Helm 3 charts
and existing releases. But there are still differences
worth testing. Some CLI flags changed. Plugin
behavior changed. Registry authentication should
be checked. And Helm 4 uses server-side apply
by default for new releases. The individual changes
are not particularly scary. The question is how
many places in your environment quietly assume
Helm 3 behavior? CI images, Argo CD, developer
machines, deployment scripts, custom plugins,
anything using the Helm SDK. This is exactly
the kind of migration that I would rather start
while nobody cares about the deadline. Put Helm
4 into a non-production pipeline. Run your existing
charts. Find the weird assumptions now. February
is plenty of time if you start in September.
It becomes considerably less time if you start
on February 9th. Fourth, Ubuntu 26.04 is now
generally available for GitHub Actions runners
on both x64 and ARM64. But the bigger change
is coming next month. GitHub is moving Ubuntu
latest from Ubuntu 24.04 to Ubuntu 26.04 between
October 19th and November 19th. So if your workflow
says runs-on: ubuntu-latest, you have effectively
told GitHub, you choose my operating system.
And GitHub is about to choose a different one.
Ubuntu 26.04 has newer tools, different versions,
and some software that is no longer preinstalled.
If your pipeline explicitly installs everything
it needs, you are probably in decent shape. If
it works because some binary happens to exist
on the runner image, you might discover a dependency
you did not know you had. GitHub recommends testing
against ubuntu-26.04 now. That is easy enough.
Change the runner label in a branch and see what
happens. If you are not ready, pin it to Ubuntu
24 .04. Neither approach is inherently wrong.
Pinning gives you stability, but upgrades become
your responsibility. Using latest gives you automatic
upgrades, but compatibility becomes your responsibility.
The problem is using a moving target while assuming
it never moves. Because your repository can remain
completely unchanged while the environment executing
it changes underneath you. Quick lightning round.
First, GitHub Actions retention changes October
1st. Checks, workflow runs, and statuses will
start following your existing Actions retention
settings, which default to 90 days. If you rely
on older CI history for auditing or debugging,
check that setting before GitHub starts cleaning
things up. Second, GitHub Advanced Security configurations
can now be enforced at the enterprise level.
That means that organizations and repository
administrators cannot override centrally enforced
security settings. Third, GitHub has added an
API showing when self-hosted Actions runner
versions lose registration and runtime support.
That is particularly timely because full minimum
version enforcement for GitHub Enterprise Cloud
begins September 25th. If you run a large self
-hosted fleet, runner lifecycle is something
you need to actively manage. And fourth, GitHub's
AI Scan for pull requests no longer requires
CodeQL default setup. It is still in public preview
for GitHub Advanced Security customers, but it
expands where GitHub's AI-powered vulnerability
detection can be used. The human closer this
week starts with a sentence almost every infrastructure
engineer has heard during an incident. But nothing
changed. The application worked yesterday. Nobody
merged anything. Nobody deployed anything. The
Terraform plan is empty. So why is the build
broken? Because “nothing changed” usually means
nothing changed in the place you were looking.
Maybe the runner image changed. Maybe a package
updated, maybe a container tag moved, maybe an
action changed, maybe a certificate expired,
maybe DNS changed, maybe an external API changed,
or maybe somebody changed the environment that
your completely unchanged code runs inside. That
is what makes the ubuntu-latest story interesting.
You can make zero changes to your repository
and still have a different operating system execute
your workflow next month. latest is a dependency.
It is just an intentionally moving dependency.
The same applies elsewhere. From Ubuntu colon
latest is a dependency. A loose Terraform provider
constraint is a dependency. Downloading the newest
version of a tool during every CI run is a dependency.
An external API is a dependency. Even time can
effectively be a dependency. Certificates expire.
Tokens expire. Support windows expire. Helm 3 can
be completely unchanged and still go from supported
software to unsupported software next February.
The answer is not to pin absolutely everything
forever because then nothing changes for three
years until you eventually have to absorb three
years of changes at once. The better approach
is deciding intentionally what is allowed to
move. If you want your CI runner to float forward,
great. Test it. If a production dependency needs
to be deterministic, pin it. If you want dependencies
The thing I keep coming back to this week is how much of our infrastructure is allowed to change without a commit ever landing in our repository.
The ubuntu-latest story is probably the cleanest example. You can have a pipeline that has been green for six months. Nobody changes the YAML. Nobody updates a dependency. Nobody merges anything. Then one morning it fails because ubuntu-latest now points at a different operating system. From Git’s perspective, nothing changed. From the system’s perspective, something pretty fundamental changed.
And I don’t think the lesson is that latest is bad. There are good reasons to let things move. If I pin a runner image forever, eventually I’m the person running a four-year-old environment because everybody is afraid to touch it. I’ve seen the same thing happen with Terraform providers, Kubernetes versions, base images, Helm, language runtimes, and basically every other dependency we use. Pinning can make today’s build reproducible, but it can also turn tomorrow’s upgrade into a much bigger project.
The better question is whether the movement is intentional.
If I’m using ubuntu-latest, I should know that I’m opting into GitHub moving that environment forward. If I’m using a loose Terraform provider constraint, I should understand what versions that constraint allows. If I’m pulling a container tag that can be overwritten, I should know that the same tag might not mean the same image tomorrow. None of those decisions are automatically wrong. They become a problem when the team thinks something is fixed when it actually isn’t.
Helm 3 is almost the opposite version of the same problem. Nothing is suddenly going to stop working when support ends in February. Your charts aren’t going to look at the calendar and refuse to deploy. That’s actually what makes end-of-life dates so easy to ignore.
The change isn’t necessarily in the software. The change is in the support around it.
Before the deadline, a security issue can get a Helm 3 patch. After the deadline, it doesn’t. Kubernetes continues moving. Client libraries continue moving. The ecosystem moves even if your Helm binary doesn’t. Eventually the gap between the environment you froze and the environment around it gets large enough that somebody has to deal with all of it at once.
That’s why I like doing these migrations when they’re still boring.
Try Helm 4 in a non-production pipeline now. Run the charts. Find the plugin somebody forgot existed. Find the script using an old flag. Find the CI image with Helm 3 baked into it. Those are cheap discoveries in September. They’re much more annoying discoveries when a security issue forces the migration later.
The GitHub workflow execution story gets at another part of this that I think platform teams are still figuring out.
We’ve spent years getting better at controlling what code can do after it starts running. We have IAM policies, short-lived credentials, protected environments, secret scanning, branch protection, OIDC, and increasingly granular permissions inside CI.
But there’s an earlier question: should this automation have started at all?
That sounds obvious, but CI systems grew up as developer tooling. You push code, the thing runs. You open a pull request, the thing runs. A bot makes a change, the thing runs.
That was fine when the pipeline compiled some code and ran unit tests.
Modern CI can assume an AWS role, push an image, sign an artifact, publish a package, modify infrastructure, or deploy production. At that point, triggering a workflow is itself a privileged operation.
That’s why I think GitHub’s execution protections are more interesting than just another Actions setting. I can say this workflow is fine for contributors to trigger, but this one isn’t. This bot can start these workflows, but not that deployment workflow. And I can evaluate the policy before enforcing it and breaking everything.
We touched pull_request_target last week, so I don’t think there’s much value in beating that particular example to death again. What matters is the direction. Last week GitHub gave us more control over what lower-trust workflows can do with caches. This week they’re giving us more control over whether workflows execute in the first place.
That’s a healthier model than treating every workflow in a repository as if it has the same trust requirements.
Then there’s the Cisco story, which is a different kind of dependency problem.
Security appliances are easy to mentally put into a separate category from the rest of our software. The email gateway is the thing protecting us. The firewall is the thing protecting us. The VPN appliance is the thing protecting us.
But they’re still software.
And in some ways they have one of the worst jobs in the environment because we’re deliberately feeding them hostile input all day.
An email gateway exists to parse email coming from people you don’t trust. A firewall processes traffic you don’t trust. A VPN concentrator accepts connections from networks you don’t control. They sit exactly where an attacker wants to interact with them.
So when one of those systems has a remotely exploitable vulnerability, the fact that it’s a security product doesn’t reduce the urgency. It can increase it.
The operational problem is that these systems also tend to become infrastructure furniture. Nobody thinks about the email gateway when it’s working. Nobody gets promoted because they upgraded the VPN appliance without incident. But everybody notices when an upgrade takes email down for an hour.
That creates a really predictable incentive to leave critical infrastructure alone.
And “don’t touch it because it works” is a strategy that works right up until it doesn’t.
I think that’s the thread connecting most of this week’s stories. Infrastructure isn’t a static collection of things we built. It’s a collection of things moving at different speeds.
GitHub changes the runner image.
Helm moves a major version forward and eventually stops maintaining the previous one.
GitHub changes what CI events and identities are allowed to execute.
Cisco releases a fix because attackers found a way through software sitting at the edge of the environment.
Your application can be completely unchanged through all of that.
That’s why I don’t really trust the phrase “nothing changed” during an incident.
I understand what people mean when they say it. Usually they mean nobody deployed the application. And that’s useful information.
But the next question should be: what else could have changed?
Did the runner change?
Did DNS change?
Did a certificate expire?
Did a secret rotate?
Did a package update?
Did an external API change?
Did a cloud provider change something underneath us?
Did a floating dependency resolve differently?
Did something reach end-of-life?
Did somebody change policy in a completely different system?
Sometimes the fastest way to get unstuck during an incident is to stop asking who changed the application and start asking what the application depends on.
And I think there’s a practical platform-engineering lesson in that too.
Know which parts of your environment are pinned.
Know which parts intentionally float.
Know which parts are controlled by somebody else.
And for the things that are supposed to move, give yourself a way to discover the change before production discovers it for you.
That might mean testing the next GitHub runner image before latest moves. It might mean automated dependency updates. It might mean tracking end-of-life dates. It might just mean having a staging environment that actually experiences upgrades instead of being pinned to exactly the same old versions as production.
The goal isn’t to stop change.
That’s impossible, and trying usually just stores up more change for later.
The goal is to make change visible enough that when something breaks at two in the morning, “nothing changed” isn’t where the investigation stops.
This week on Ship It Weekly: GitHub Actions workflow execution protections are now generally available, giving organizations more control over who and what can trigger individual workflows. Cisco is patching critical vulnerabilities in Secure Email Gateway, including an actively exploited issue that can lead to remote command execution as root. Helm 3 has reached its final minor release and is heading toward end-of-life in February 2027. And GitHub’s ubuntu-latest Actions runner is preparing to move from Ubuntu 24.04 to 26.04.
The bigger theme this week is infrastructure that changes even when your code does not. GitHub is making CI execution permissions more explicit, Helm teams now have a defined migration deadline, and the ubuntu-latest transition is a good example of how a completely unchanged workflow can suddenly be running in a different environment. Pinning everything forever is not necessarily the answer. The important part is knowing which dependencies are allowed to move and testing those changes deliberately.
In the lightning round: GitHub Actions checks, workflow runs, and statuses will begin following your configured retention period on October 1. GitHub Advanced Security can now enforce configurations from the enterprise level. GitHub added API support for tracking when self-hosted Actions runner versions lose support. And AI Scan for pull requests can now be used without requiring CodeQL default setup.
And the human closer starts with a sentence almost every infrastructure engineer has heard during an incident: “But nothing changed.” Maybe nothing changed in the application, but the runner image changed, a dependency moved, a certificate expired, DNS changed, or an external service behaved differently. Latest tags, loose version constraints, external APIs, and even support windows are dependencies. The goal is not to freeze everything forever. It is to avoid accidental mutability, where something can change without the team realizing it was ever allowed to change.

The thing I keep coming back to this week is how much of our infrastructure is allowed to change without a commit ever landing in our repository.
The
ubuntu-lateststory is probably the cleanest example. You can have a pipeline that has been green for six months. Nobody changes the YAML. Nobody updates a dependency. Nobody merges anything. Then one morning it fails becauseubuntu-latestnow points at a different operating system. From Git’s perspective, nothing changed. From the system’s perspective, something pretty fundamental changed.And I don’t think the lesson is that
latestis bad. There are good reasons to let things move. If I pin a runner image forever, eventually I’m the person running a four-year-old environment because everybody is afraid to touch it. I’ve seen the same thing happen with Terraform providers, Kubernetes versions, base images, Helm, language runtimes, and basically every other dependency we use. Pinning can make today’s build reproducible, but it can also turn tomorrow’s upgrade into a much bigger project.The better question is whether the movement is intentional.
If I’m using
ubuntu-latest, I should know that I’m opting into GitHub moving that environment forward. If I’m using a loose Terraform provider constraint, I should understand what versions that constraint allows. If I’m pulling a container tag that can be overwritten, I should know that the same tag might not mean the same image tomorrow. None of those decisions are automatically wrong. They become a problem when the team thinks something is fixed when it actually isn’t.Helm 3 is almost the opposite version of the same problem. Nothing is suddenly going to stop working when support ends in February. Your charts aren’t going to look at the calendar and refuse to deploy. That’s actually what makes end-of-life dates so easy to ignore.
The change isn’t necessarily in the software. The change is in the support around it.
Before the deadline, a security issue can get a Helm 3 patch. After the deadline, it doesn’t. Kubernetes continues moving. Client libraries continue moving. The ecosystem moves even if your Helm binary doesn’t. Eventually the gap between the environment you froze and the environment around it gets large enough that somebody has to deal with all of it at once.
That’s why I like doing these migrations when they’re still boring.
Try Helm 4 in a non-production pipeline now. Run the charts. Find the plugin somebody forgot existed. Find the script using an old flag. Find the CI image with Helm 3 baked into it. Those are cheap discoveries in September. They’re much more annoying discoveries when a security issue forces the migration later.
The GitHub workflow execution story gets at another part of this that I think platform teams are still figuring out.
We’ve spent years getting better at controlling what code can do after it starts running. We have IAM policies, short-lived credentials, protected environments, secret scanning, branch protection, OIDC, and increasingly granular permissions inside CI.
But there’s an earlier question: should this automation have started at all?
That sounds obvious, but CI systems grew up as developer tooling. You push code, the thing runs. You open a pull request, the thing runs. A bot makes a change, the thing runs.
That was fine when the pipeline compiled some code and ran unit tests.
Modern CI can assume an AWS role, push an image, sign an artifact, publish a package, modify infrastructure, or deploy production. At that point, triggering a workflow is itself a privileged operation.
That’s why I think GitHub’s execution protections are more interesting than just another Actions setting. I can say this workflow is fine for contributors to trigger, but this one isn’t. This bot can start these workflows, but not that deployment workflow. And I can evaluate the policy before enforcing it and breaking everything.
We touched
pull_request_targetlast week, so I don’t think there’s much value in beating that particular example to death again. What matters is the direction. Last week GitHub gave us more control over what lower-trust workflows can do with caches. This week they’re giving us more control over whether workflows execute in the first place.That’s a healthier model than treating every workflow in a repository as if it has the same trust requirements.
Then there’s the Cisco story, which is a different kind of dependency problem.
Security appliances are easy to mentally put into a separate category from the rest of our software. The email gateway is the thing protecting us. The firewall is the thing protecting us. The VPN appliance is the thing protecting us.
But they’re still software.
And in some ways they have one of the worst jobs in the environment because we’re deliberately feeding them hostile input all day.
An email gateway exists to parse email coming from people you don’t trust. A firewall processes traffic you don’t trust. A VPN concentrator accepts connections from networks you don’t control. They sit exactly where an attacker wants to interact with them.
So when one of those systems has a remotely exploitable vulnerability, the fact that it’s a security product doesn’t reduce the urgency. It can increase it.
The operational problem is that these systems also tend to become infrastructure furniture. Nobody thinks about the email gateway when it’s working. Nobody gets promoted because they upgraded the VPN appliance without incident. But everybody notices when an upgrade takes email down for an hour.
That creates a really predictable incentive to leave critical infrastructure alone.
And “don’t touch it because it works” is a strategy that works right up until it doesn’t.
I think that’s the thread connecting most of this week’s stories. Infrastructure isn’t a static collection of things we built. It’s a collection of things moving at different speeds.
GitHub changes the runner image.
Helm moves a major version forward and eventually stops maintaining the previous one.
GitHub changes what CI events and identities are allowed to execute.
Cisco releases a fix because attackers found a way through software sitting at the edge of the environment.
Your application can be completely unchanged through all of that.
That’s why I don’t really trust the phrase “nothing changed” during an incident.
I understand what people mean when they say it. Usually they mean nobody deployed the application. And that’s useful information.
But the next question should be: what else could have changed?
Did the runner change?
Did DNS change?
Did a certificate expire?
Did a secret rotate?
Did a package update?
Did an external API change?
Did a cloud provider change something underneath us?
Did a floating dependency resolve differently?
Did something reach end-of-life?
Did somebody change policy in a completely different system?
Sometimes the fastest way to get unstuck during an incident is to stop asking who changed the application and start asking what the application depends on.
And I think there’s a practical platform-engineering lesson in that too.
Know which parts of your environment are pinned.
Know which parts intentionally float.
Know which parts are controlled by somebody else.
And for the things that are supposed to move, give yourself a way to discover the change before production discovers it for you.
That might mean testing the next GitHub runner image before
latestmoves. It might mean automated dependency updates. It might mean tracking end-of-life dates. It might just mean having a staging environment that actually experiences upgrades instead of being pinned to exactly the same old versions as production.The goal isn’t to stop change.
That’s impossible, and trying usually just stores up more change for later.
The goal is to make change visible enough that when something breaks at two in the morning, “nothing changed” isn’t where the investigation stops.
It’s where it starts.
Related Ship It Weekly Episodes